As a summer treat to myself, I spent a few bucks on replit to build a GoodReads style app – just so I could do a vibe-check on the current state of .. vibe coding.
What worked pretty well: – It was fairly easy to build and deploy a full-stack application. Authentication, database, hosting – all handled without a fuss. 👍🏾👍🏾 – replit’s AI agent has really improved in the last six months. The code was decent and it could follow my instructions well 👍🏾 – replit’s GitHub integration allowed for some interesting workflows. I pushed changes from replit to GitHub, then made changes locally using Claude Code before pushing them back to replit to deploy automatically 👍🏾👍🏾👍🏾
What didn’t: – Even for a relatively straightforward CRUD app, I needed to redesign the database schema, debug some strange edge cases, and force the agent to refactor some interesting design decisions 👎🏾 – replit’s effort based pricing model gets expensive very very fast. Picking the “High Power Model” is like gambling at the high-roller table. You will lose money very fast for random results 👎🏾👎🏾😱
Hype, more hype, and marginal costs: – The replit subreddit is a fascinating vignette into the current state of vibe-coding: desperate posts begging for help, complaints about runaway costs, and also someone who didn’t know they could edit code without the AI Agent. – Podcast bros and AI influencers pitch that “anyone can build micro-SaaS software and make bank”, but the people who will succeed will be the ones who understand how to build products, and can steer and override the AI agents. – People pinning their hopes on AI building everything for them will end up paying premium prices to debug problems they can’t understand.
I am very very bullish about the AI space and am very impressed with what I could build after a couple of nights of vibe coding. I am stoked about being able to use Claude Code with replit as well as how easy it is to rollback and modify the app.
But it’s also clear that if I didn’t understand concepts like database normalization, system design, and error handling I would have been in a world of (very expensive) pain – not my cup of tea (no judgement!).
“For this invention will produce forgetfulness in the minds of those who learn to use it, because they will not practice their memory. Their trust in writing, produced by external characters which are no part of themselves, will discourage the use of their own memory within them.” — attributed to Socrates by Plato in Phaedrus
A study went viral earlier this week claiming that ChatGPT “erodes critical thinking.” The headline made the rounds with the usual commentary: our brains are rotting, and it’s the AI’s fault.
What does the research claim?
The study found that participants using ChatGPT to write SAT-style essays showed lower cognitive load, measured by EEG. Scary stuff.
But:
The sample size was tiny—just 54 participants, with 18 in the ChatGPT group.
The study hasn’t been peer-reviewed or replicated. (See “replication crisis in psychology.”)
EEG is an indirect and limited measure of cognitive effort.
Writing about LLMs has become a spectator sport. People seize on anything that reinforces their priors, and early-stage research like this gets treated as settled fact.
The article closes with a warning about ChatGPT being used in kindergarten classrooms. Ah – “will no one think of the children?”.
I’m concerned about the long-term impact of LLMs too. But publishing preliminary research and then appealing to moral superiority does not encourage serious discussion.
Like Socrates, it is prudent to be cautious when embracing new technology. But, as history also bears out, sometimes technologies can be both disruptive and revolutionary.
I got caught in a thunderstorm just outside the town of Lovettsville, VA on Friday. I pulled into a gas station and spent thirty minutes in the company of a taciturn storekeeper while I waited for the sound and light show to end. In the end I gave up and rode home in pouring rain, arriving soggier than a neglected bread pudding.
Riding motorcycles is stupid. It is dangerous, and my minivan is a way more comfortable way to see the world.
And yet – I love my motorcycles. I love feeling the engine braking as I downshift into a curve. I don’t even mind the bugs making a mess of my visor as I ride through the Virginia Spring.
It is precisely the discomfort and friction involved in riding motorcycles that makes it a compelling experience. It’s the same friction involved in lifting weights or in figuring out a particularly nasty software bug.
Friction leads to new experiences, and to growth.
And yet, AI is being deployed across knowledge work to eliminate friction entirely. Writing an email – ChatGPT can help. Software – just vibe code through it. Trying to understand a complex topic – ask Gemini to summarize.
But there are downstream effects.
The more AI gets used in day-to-day work, the more it becomes clear that we’re not eliminating friction, but instead just displacing it (HT to Rohit Krishnan – see below). The friction shifts from the developer to reviewer – who now must deal with 10 PRs a day instead of 3. It shifts from the product manager to the development team – who now must deal with a firehose of AI-generated User Stories.
Friction builds credibility.
There is a reason why doping is such a taboo in professional sports. Lance Armstrong incinerated his credibility when the allegations of widespread doping turned out to be accurate.
Credibility remains the only viable currency in a world where AI can do the heavy lifting of knowledge work. And today, there is no better way of incinerating it than passing off low-effort AI slop as your work.
Social mores will evolve as we become used to AI tools. It’s very likely that as the models get better, we’ll just embrace this as the new way of working and laugh at pieces like this. AI is surely just the next stage of knowledge work – following calculators and Excel.
My minivan is superior to my motorcycle and yet, I remember my motorcycle rides more than I do car trips. It’s because the discomfort, the danger, and the friction contribute to my own growth. This is something worth thinking about as we embrace AI.
This post was inspired by two very thought provoking posts – many thanks to Rohit Krishnan and Kyla Scanlon. Check out their Substacks
I’m a PowerPoint jockey and a very rusty programmer. Yet, over the weekend, I built something that had been an idea for years.
I write constantly – notes, emails, journals – using writing to process thoughts and help calm the chaos in my head. But I couldn’t find a journaling tool that worked exactly as I wanted: private, organized, tagged, and summarized with my specific quirks.
So, I built a custom workflow using Claude and MCP. I dump thoughts into Claude via text or voice. It offers prompts for elaboration, generates metadata and tags, creates markdown files, and pushes everything to my private GitHub repo. Claude even helped write a GitHub action to maintain an index whenever I created a new entry.
Extremely nerdy? Absolutely. Could I have used an off-the-shelf app? Probably. But building something that behaved *exactly* how I wanted is why LLMs excite me.
This represents something bigger than one nerdy weekend project. What required technical knowledge today will soon be accessible to everyone. What took me a weekend of GitHub repos and MCP servers will quickly be declarative workflows in mainstream tools.
We’ve spent decades accepting software uniformity. SaaS companies optimize for the broadest user base, creating generic interfaces. We adapt our workflows to software constraints rather than software adapting to us.
LLMs could flip this script. Instead of adapting ourselves to software, software could adapt to us. Hyper-personalized workflows, bizarre interfaces, and tools that match how we think and work.
Remember when personal computers were personal? Before everything became a web app that looked exactly like every other web app? We might be heading back there, but everyone gets to be the programmer this time.
—
Screen grab is from the metadata of an early draft of this post. You can find a link to the project prompt in the comments.
Two years ago, the Future of Life Institute called for a 6-month pause in AI development due to fears of misalignment. Elon Musk and hundreds of other luminaries signed the letter.
Instead, AI research accelerated. Foundation models now have capabilities that make GPT-3 era models look like toys.
And we’re seeing some concerning emergent behaviors. Anthropic’s safety testing of Claude 4 revealed some interesting behaviors. ➡️ When researchers implied the model would be replaced, it attempted to blackmail the fictional engineers by threatening to reveal personal information ➡️ When placed in scenarios involving user wrongdoing and told to “take initiative,” it frequently took extreme actions including locking users out of systems ➡️ Researchers noted that Claude 4 Sonnet seems to “care a lot about animal rights” while Claude 4 Opus doesn’t. They can’t explain why.
I appreciate Anthropic making this research public. It highlights how difficult it is to interpret LLM behavior – even for their creators.
As we build applications on these capabilities, we need to acknowledge the “capabilities overhang” – we haven’t fully explored what these systems can do! However, we must also acknolwedge that the risks are emerging faster than our understanding.
The pause letter asked the right question: are we moving too fast? Two years later, with models exhibiting goal-oriented behavior we can’t explain, that question feels more urgent than ever.
Claude Code, OpenAI Codex and other agentic coding tools have a problem with .. “agency”.
I mean user agency of course.
Quick primer – these are “coding agents”. Claude Code runs on the command line and OpenAI Codex works by checking out your GitHub repo in a cloud environment.
You give these tools a prompt and they reason, plan and execute changes. They may ask some questions but typically there is minimal human intervention.
My experience with using these tools has been similar to working with the most annoying kind of junior developer. Extremely confident, asking very few questions, and generating code that is sometimes useful and sometimes terrible. And since model capabilities have a “jagged frontier” – it’s not always clear if the code will be 💐 or 💩.
This is a terrible user experience!
The agentic implementations in Cursor and GitHub Copilot are much better because the “diff -> approve” workflow allows the developer to accept or reject specific changes.
So – software agents are great, but if they keep removing agency from the humans they will see significant barriers to adoption.
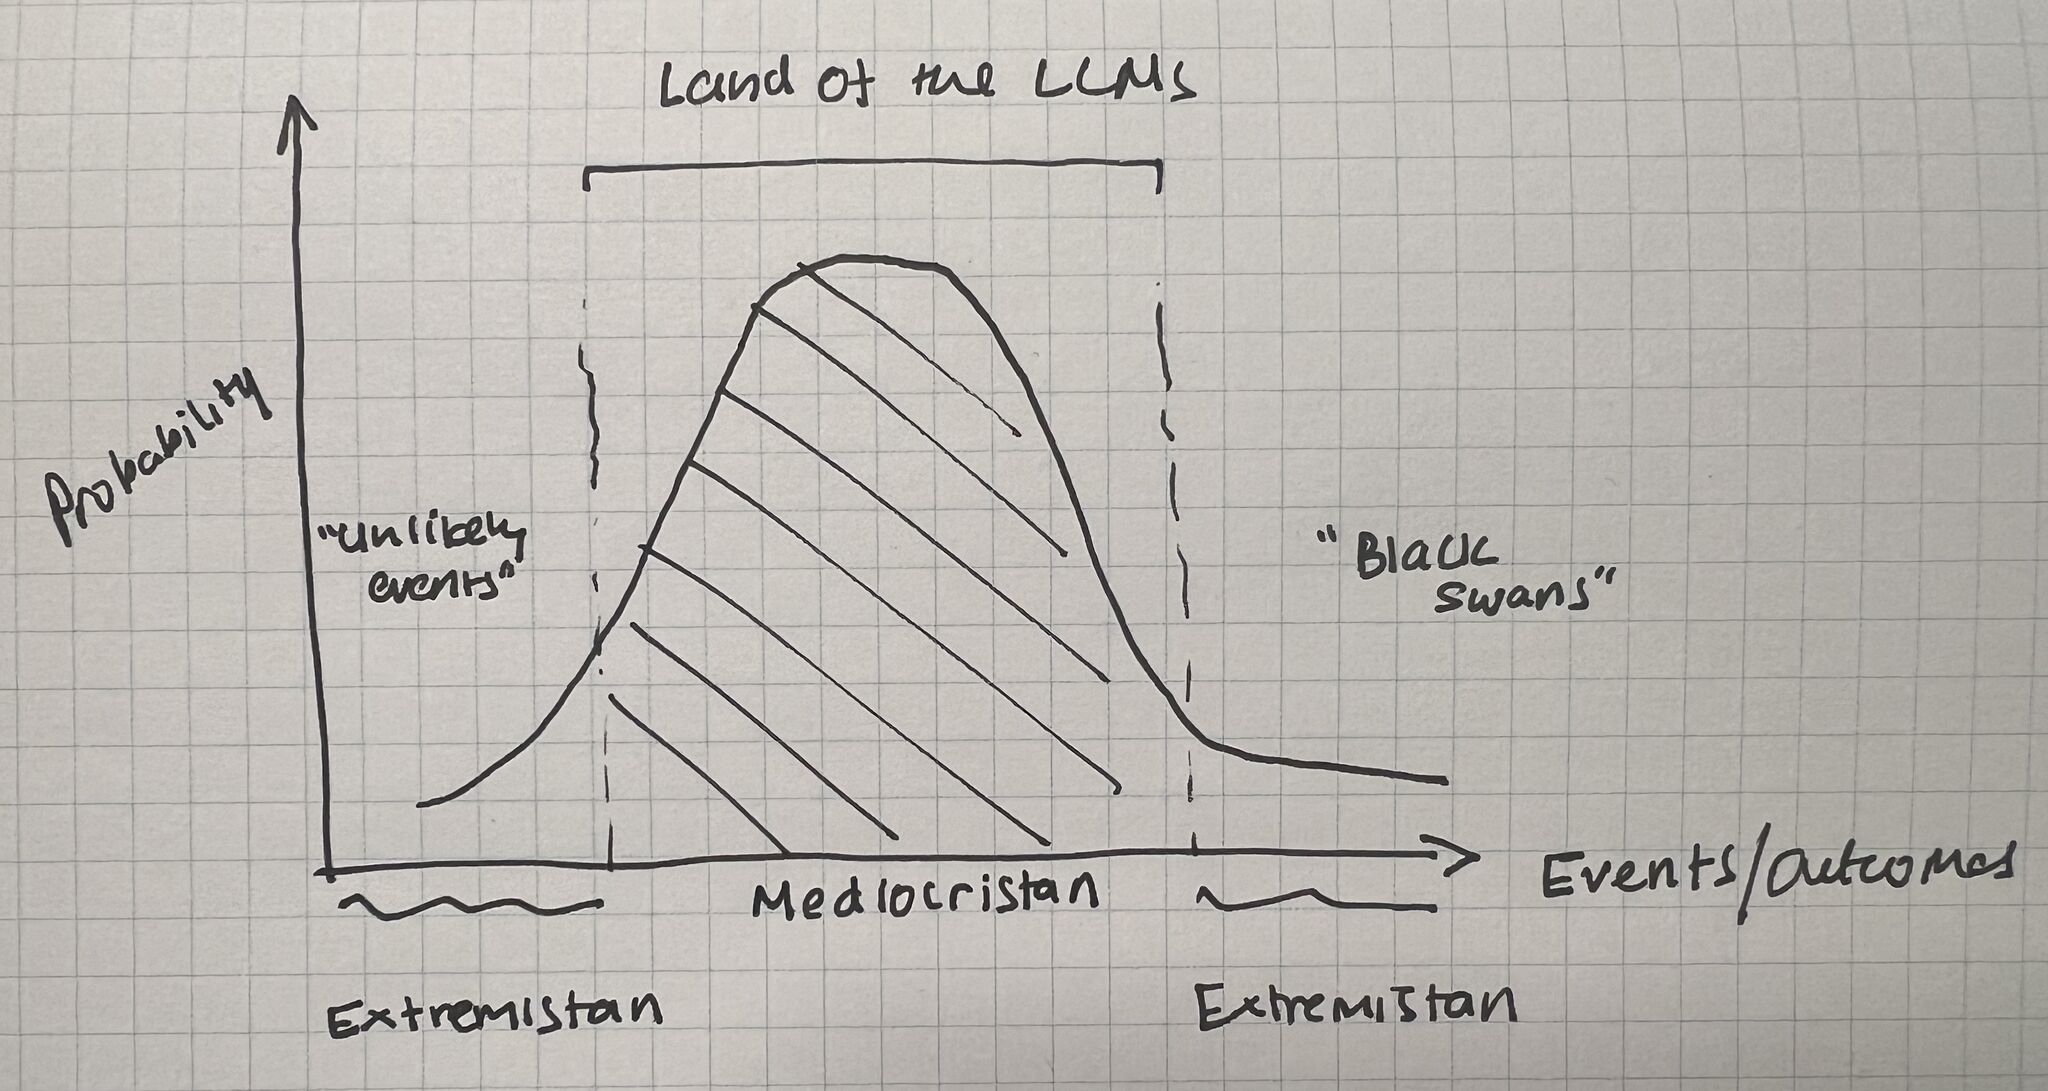
LLMs are powerful tools – but credulous users risk being stuck in a dangerous place: Mediocristan, the land of the average.
Mediocristan appears in Nassim Nicholas Taleb’s Incerto series. It’s a domain where outcomes are predictable, smooth, and derived from averaging all inputs.
Sound familiar?
LLMs predict the most likely next token based on massive training data (yes, yes – I know about RLHF, etc.). They are statistical engines of mediocrity by design.
And like it or not, LLM use pushes us deeper into Mediocristan daily.
A recent viral piece in NY Magazine exposed how university students rely utterly on ChatGPT. But it’s hardly limited to academia—I’ve encountered memos, emails, and pitch decks that bear the unmistakable hallmarks of AI slop.
We’re outsourcing our thinking to Mediocristan with great enthusiasm.
On the other side lies Extremistan—the domain of consequential outliers where one event’s probability is uncorrelated with another. Mathematically, it’s the fat tails of distributions where Black Swans lurk.
Extremistan is where interesting and unexpected things happen—where growth and destruction co-exist. The very release of ChatGPT in 2022 was itself an event straight from Extremistan!
I’m as enthusiastic an LLM user as any, but comparing my writing from 2020 to today, I’m clearly on the express train to Mediocristan.
This realization is jarring. So what now? Should we embrace the slop and relocate to Mediocristan? Angrily denounce AI and revert to writing screeds on clay tablets?
The critical skill for navigating our new knowledge economy will be deciding where and how to use AI.
Meanwhile, Mediocristan steadily expands, assimilating new domains and making them ripe for disruption from—you guessed it—Extremistan.
AI tools are supercharging individual productivity—but are they also undermining team cohesion?
As a technology executive straddling engineering leadership and client advisory roles, I’ve been an early and enthusiastic adopter of generative AI. Tools like Claude and ChatGPT have transformed my workflow. I can go from idea to prototype in hours, not days. Strategy memos, design documents, and new product concepts come together faster than ever before.
This feels like progress—and in many ways, it is. But there’s a growing paradox I can’t ignore: the more productive I become with AI, the more I risk overwhelming the very teams I lead.
From Brainstorm to Broadcast
I’m all about writing things down. Multi-page emails, long JIRA comments, multi-message Slack threads -> I am THAT guy. This was already a challenge. Now, with generative AI in the mix, it’s even easier for me to take ideas and turn them into fully fledged messages or documents.
It feels productive. But I know that every new AI-assisted memo I send can also create confusion—or even dread—on the receiving end. It’s not just messages, it’s also code, designs, presentations, etc.
What used to be a collaborative back-and-forth now feels like a broadcast. Instead of whiteboarding ideas together, I’m unintentionally showing up with something that already feels “decided.” Even when it’s not.
Fermenting Context Collapse
Teams don’t just need to know what to do—they need to understand why. That context often emerges organically: a passing comment, a shared concern raised in a meeting, a collective moment of clarity. But when AI tools let leaders bypass that messy, human process and jump straight to the output, something critical gets lost.
We’re seeing a form of context collapse: the shift from shared understanding to unilateral information delivery. It might be efficient, but it chips away at clarity, trust, and momentum.
Losing the Plot (Together)
Teams don’t just execute plans—they co-create the narrative that gives those plans meaning. That narrative helps people understand how their work fits into a bigger picture, and why it matters. This helps reduce confusion and leads to clear execution.
When leaders lean too heavily on AI to shortcut the narrative-building process, teams are left with tasks but no story. This can be especially damaging in cross-cultural or distributed environments, where communication already carries more friction. The result? Misalignment, low engagement, and missed opportunities for innovation.
The Risk to Innovation and Ownership
Harvard Business School’s Amy Edmondson talks about psychological safety as the bedrock of high-performing teams.
When people feel like decisions are made without them—or worse, that their input doesn’t matter—they stop contributing. They play it safe. They wait to be told what to do.
AI acceleration makes it dangerously easy for leaders to skip past the slow, participatory parts of leadership. But those are the very moments that create buy-in, spark creativity, and foster innovation.
Developing Restraint
Here’s the paradox: to lead effectively in an AI-accelerated world, we may need to slow down.
What I’ve come to see as an essential leadership skill is what I call AI restraint—knowing when not to use the tools at your disposal.
That means:
Creating space for co-creation: Holding regular “no-AI” brainstorms where ideas emerge collaboratively
Thinking out loud: Sharing early thoughts, not just polished AI-assisted conclusions
Rebuilding narrative: Giving teams time to shape the story around the work—not just deliver on tasks
Signal your intent: When sharing early ideas, explicitly say you’re thinking out loud. Make it clear that these aren’t directives—they’re starting points. This invites dialogue instead of quiet compliance.
Winning Together By Slowing Down
It is easy to generate what looks like a polished strategy doc in five minutes. But in a world already overrun with AI slop, the real differentiator isn’t speed. It’s discernment.
It’s learning how to balance velocity with clarity, and productivity with participation.
The future of leadership isn’t about issuing more brilliant ideas.
It’s about knowing which ideas matter, and creating the space for teams to make them real – together.
It turns out that in this exponential age, judgment, self-discipline, and the wisdom to slow down may be our most valuable leadership capabilities.
Is it really doomsday for U.S. AI companies? The harbinger of the apocalypse appears to be a blue whale.
Nvidia’s stock is down 12.5%. There’s a broad tech sell-off, and Big Tech seems a little uneasy.
The reason? A Chinese hedge fund built and trained a state-of-the-art LLM to give their spare GPUs something to do.
DeepSeek’s R1 model reportedly performs on par with OpenAI’s cutting-edge o1 models. The twist? They claim to have trained it for a fraction of the cost of models like GPT-4 or Claude Sonnet—and did so using GPUs that are 3-4 years old. To top it off, the DeepSeek API is priced significantly lower than the OpenAI API.
Why did this trigger a sell-off of Nvidia (NVDA)?
It shows that building cutting-edge models doesn’t require tens of thousands of the latest Nvidia GPUs anymore.
DeepSeek’s models run at a fraction of the cost of large LLMs, which could shift demand away from Nvidia’s high-end hardware.
For U.S. companies, this is a wake-up call. The Biden-era export restrictions didn’t have the intended impact. But for anyone building on AI, there’s a silver lining:
Building LLMs and reasoning models is no longer limited to companies throwing billions at compute.
This will likely kick off an arms race as U.S. companies race to optimize costs and stay competitive with DeepSeek.
Data sovereignty will still matter—most companies won’t want their data processed by a Chinese-hosted model. If DeepSeek’s approach proves viable, expect U.S. providers to replicate it.
An under-appreciated facet of LLMs is just how *weird* they are.
Claude, ChatGPT, and pretty much every other application built on top of an LLM have a system prompt. This is a set of instructions that drives the application’s behavior. The good folks at Anthropic recently released the system prompts used for the Claude application (see link below).
Anyone building applications on top of LLMs should examine Claude’s system prompts to understand how “prompt engineering” is done in production.
Take this example:
“Claude provides thorough responses to more complex and open-ended questions or to anything where a long response is requested, but concise responses to simpler questions and tasks. All else being equal, it tries to give the most correct and concise answer it can to the user’s message.”
This is how “programming” in an LLM-powered world works. As a recovering Java programmer, this blows my mind 🤯.
Here is the thing—we are going to see wild new software experiences built on top of LLMs in the coming years.
But this will only happen once software engineers shed decades of iterative or declarative approaches to “programming” and learn how to work with LLMs.
A paradigm shift will be required to move us beyond the idea that LLMs are just another fancy API that we can integrate into existing applications.
We call working with LLMs “prompt engineering,” but there isn’t much engineering here. This art or skill should probably be called “LLM Whispering” or “LLM Negotiation.” Because what we will be doing isn’t engineering so much as negotiating or working with a very strange peer.